AI inference chips are becoming a product decision, not just a line item in a capacity plan. A model can have strong reasoning, a good UI, and useful tools, then still feel broken if the first token arrives slowly or every tool call adds another pause. That is why accelerators, memory systems, quantization formats, and serving software now compete on the user-visible path from request to response.
Why AI inference chips now define product feel
Inference starts after training ends. It covers the repeated work of turning a live prompt into tokens, images, classifications, embeddings, or tool decisions. For chat products, two measurements matter more than a headline FLOPS number: time to first token (TTFT) and inter-token latency. TTFT controls whether a person thinks the system heard them. Inter-token latency controls whether a streamed answer reads like a response or a progress bar.
The difference compounds in an agent. A single request may prompt a model, trigger retrieval, call a tool, inspect the result, and generate a final answer. If each stage adds 300 milliseconds, five stages add 1.5 seconds before network overhead and queue time. A lower-latency model server can therefore change which interactions a product can reasonably offer: inline code completion, voice turn-taking, live search, copilot suggestions, and multi-step automation.
Batching complicates the picture. Large batches improve accelerator utilization and total tokens per second, but can make an individual request wait behind other work. That trade-off is fine for overnight document processing. It is painful for an interactive editor. The winning setup is rarely the one with the biggest peak throughput. It is the one that holds a latency target at the expected concurrency.
What the hardware is actually changing
AI inference chips need to move weights and key-value cache data as reliably as they multiply matrices. Many large language model requests become memory-bandwidth constrained during token generation: each new token reuses model weights and extends the cache that stores prior attention state. More compute alone does not solve that bottleneck. HBM capacity, HBM bandwidth, the accelerator interconnect, and the runtime scheduler all affect the result.
Low-precision formats are one direct response. NVIDIA describes NVFP4 as a 4-bit format with FP8 scaling and 16-value micro-blocks. Its published figures say NVFP4 can cut model memory use by about 3.5x versus FP16 and 1.8x versus FP8, while its DeepSeek-R1-0528 benchmarks stayed within 1% of FP8 accuracy. Those numbers do not guarantee the same result for every model, but they show why precision format has become a serving decision. Fewer bytes per weight can put a larger model on one device or free memory for more concurrent sequences.
Cloud providers are taking the same path with purpose-built silicon. Google says its sixth-generation Trillium TPU improves compute performance per chip by up to 4.7x over TPU v5e and increases high-bandwidth memory capacity and bandwidth. AWS reports that Inferentia2 delivers up to four times the throughput and up to ten times lower latency than Inferentia1. These are vendor comparisons, so they should be treated as platform-specific claims rather than a universal leaderboard. Still, the direction is clear: silicon vendors are selling response behavior and economics, not only peak arithmetic.
Measure the request path, not the brochure
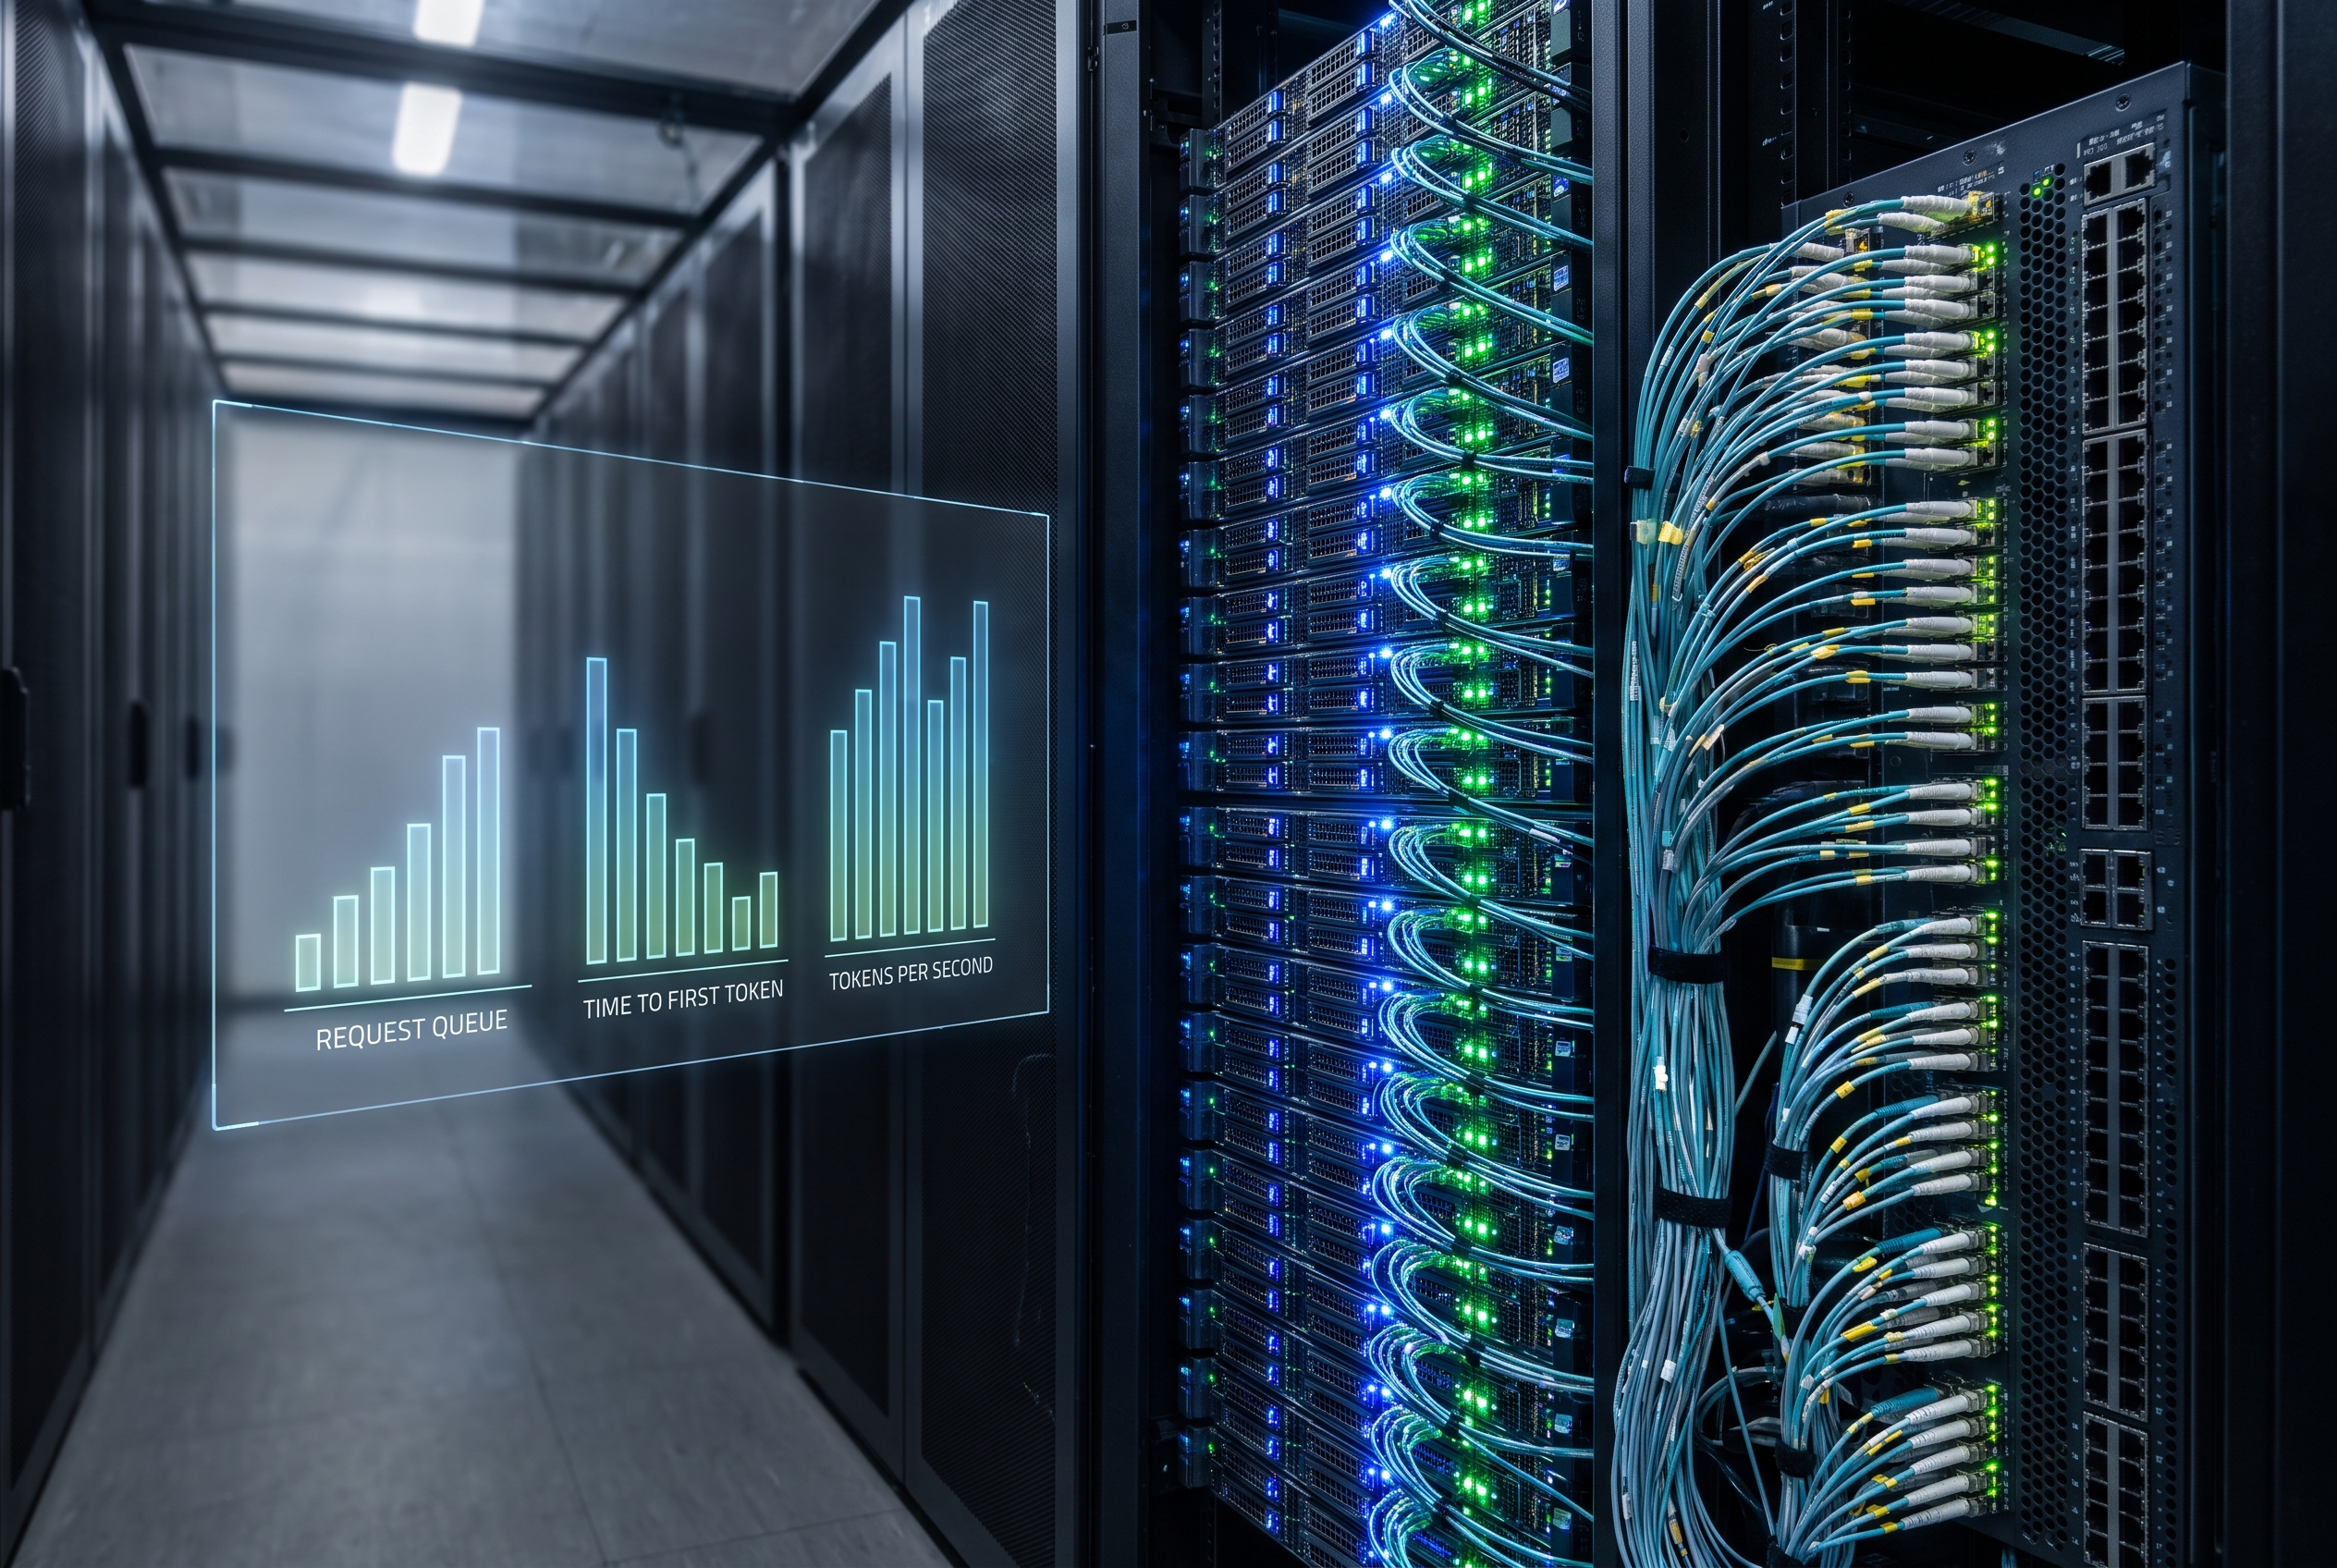
Developers should split a benchmark into at least four numbers. First, record p50 and p95 TTFT at realistic concurrency. Second, record generated tokens per second after the stream begins. Third, capture end-to-end latency, including API gateway, retrieval, tool execution, and safety checks. Fourth, track queue time separately. A fast accelerator cannot hide an overloaded admission queue.
Use fixed prompt lengths and output lengths when comparing stacks. A 200-token prompt with a 50-token answer stresses a different part of the system than a 20,000-token retrieval prompt. Also test cold and warm cache behavior. Cold starts, model loading, and prefix-cache misses often dominate the experience that a new customer sees.
Cost needs the same care. Cost per million tokens is useful, but it hides idle capacity, retries, and overprovisioning for a p95 objective. A smaller accelerator cluster that keeps TTFT below one second may be a better product choice than a larger cluster optimized only for aggregate throughput. For long-context traffic, key-value cache growth can become the capacity limit before raw compute does.
Practical choices for infrastructure teams
Start by classifying traffic. Keep interactive chat, code completion, and voice workloads in a latency-sensitive pool. Route bulk summarization, embedding backfills, and offline media jobs to a throughput-oriented pool. This avoids letting a large batch turn every customer-facing request into a tail-latency event.
Then set service-level objectives that describe what people feel. For example, an interactive assistant might target p95 TTFT below 1.5 seconds and p95 token gaps below 100 milliseconds. The right targets depend on the product and model, but the key is to publish them before choosing hardware. That makes procurement and runtime tuning testable.
Choose model format and serving engine together. Quantization may lower memory traffic, but it can shift quality, kernel support, or deployment complexity. Test the exact model, context length, batch policy, and hardware generation planned for production. Keep a quality evaluation beside the latency dashboard so a lower number does not quietly degrade factuality or tool-use reliability.
Finally, make observability part of the feature. Break down each trace into queue, prefill, decode, retrieval, tool, and network time. Alert on p95 and p99, not only averages. That data tells an infrastructure team whether to add capacity, change batching, upgrade an accelerator, cache a prefix, or fix a slow downstream service.
AI inference chips will keep changing, but the buying question is stable: can this stack produce the response time the product promises at real load? Teams that benchmark the full request path will make better calls than teams that compare a single peak-throughput number. Explore and run AI models directly on Wiro.