GPT 6 Astra puts a 1,050,000-token context window into an agent-shaped model, but the useful change is not simply that a prompt can get huge. It changes how teams can keep requirements, evidence, tool results, screenshots, and code history available during a long job. The Wiro model listing pairs that window with image input, tool calling, and five reasoning settings, from low through max. That combination matters when an agent must do more than answer a question: it must inspect, decide, act, and leave a trail another person can review.
What GPT 6 Astra long context changes
A million-token window does not mean every job needs a million tokens. It does mean an agent can start with a wider working set. A repository, product specification, incident timeline, runbook, and the last ten tool outputs can stay closer together instead of being split into many retrieval calls. That reduces one common failure mode: an agent fixes the latest symptom while missing a constraint buried in an earlier document.
OpenAI describes Astra as a model for computer use, browsing, software engineering, cybersecurity, science, and professional work. Its launch materials also describe an experimental Codex feature that preserves notes across filled context windows and lets the model search earlier windows. That is a more realistic picture of long-running work than a single giant prompt. The session still needs structure. The agent needs a durable record of decisions, tool output, and unresolved questions.
The key design shift is from retrieval as a one-time preamble to retrieval as a controlled loop. Keep stable material near the front: system rules, schemas, tool definitions, and the current plan. Add volatile evidence later. Ask the model to name which sources support each conclusion. If a source conflicts with another, make it report that conflict rather than silently average the two.
The infrastructure bill behind a larger window
Long context moves pressure into memory movement. Each token contributes key-value state that inference servers must retain or move while the model generates. More context can improve task continuity, but it can also increase time to first token, memory demand, and queue contention. For infrastructure teams, that makes median output speed only part of the picture. Track input tokens, cached-input share, time to first token, tool-call latency, completion rate, and the cost of a finished task.
Prompt caching helps when a workflow repeats the same prefix. OpenAI explains that caching stores key-value state for a matching prompt prefix rather than the raw tokens. A stable prefix can avoid recomputing that work, reduce input cost, and shorten startup latency. The catch is strict matching. A changed tool schema, reordered instructions, or altered early message can break reuse. Put stable instructions and tool definitions first. Put per-task documents and fresh user data after them.
There is also a governance cost. A wide context can contain secrets, stale policies, untrusted webpages, and conflicting instructions. Context length does not turn those inputs into trusted facts. Segment sensitive material, apply access controls before it reaches the model, and treat retrieved text as data. An agent should not gain authority just because it can see more history.
Developer workflows that benefit
Large refactors. A coding agent can keep architecture notes, failing tests, dependency constraints, and code-review feedback in view. That helps when a change spans multiple packages and a local fix would violate an API contract. The useful test is not whether it writes a patch. Test whether it can explain the dependency path, run the relevant checks, and stop when an approval boundary appears.
Incident investigation. Feed a bounded incident packet: alert timeline, deployment changes, metrics snapshots, relevant logs, and the active runbook. Ask for a ranked hypothesis list with evidence links, then let the agent call read-only diagnostic tools. Do not begin with production write access. A model that can remember 1.05 million tokens can still make a wrong causal claim if the timeline is noisy.
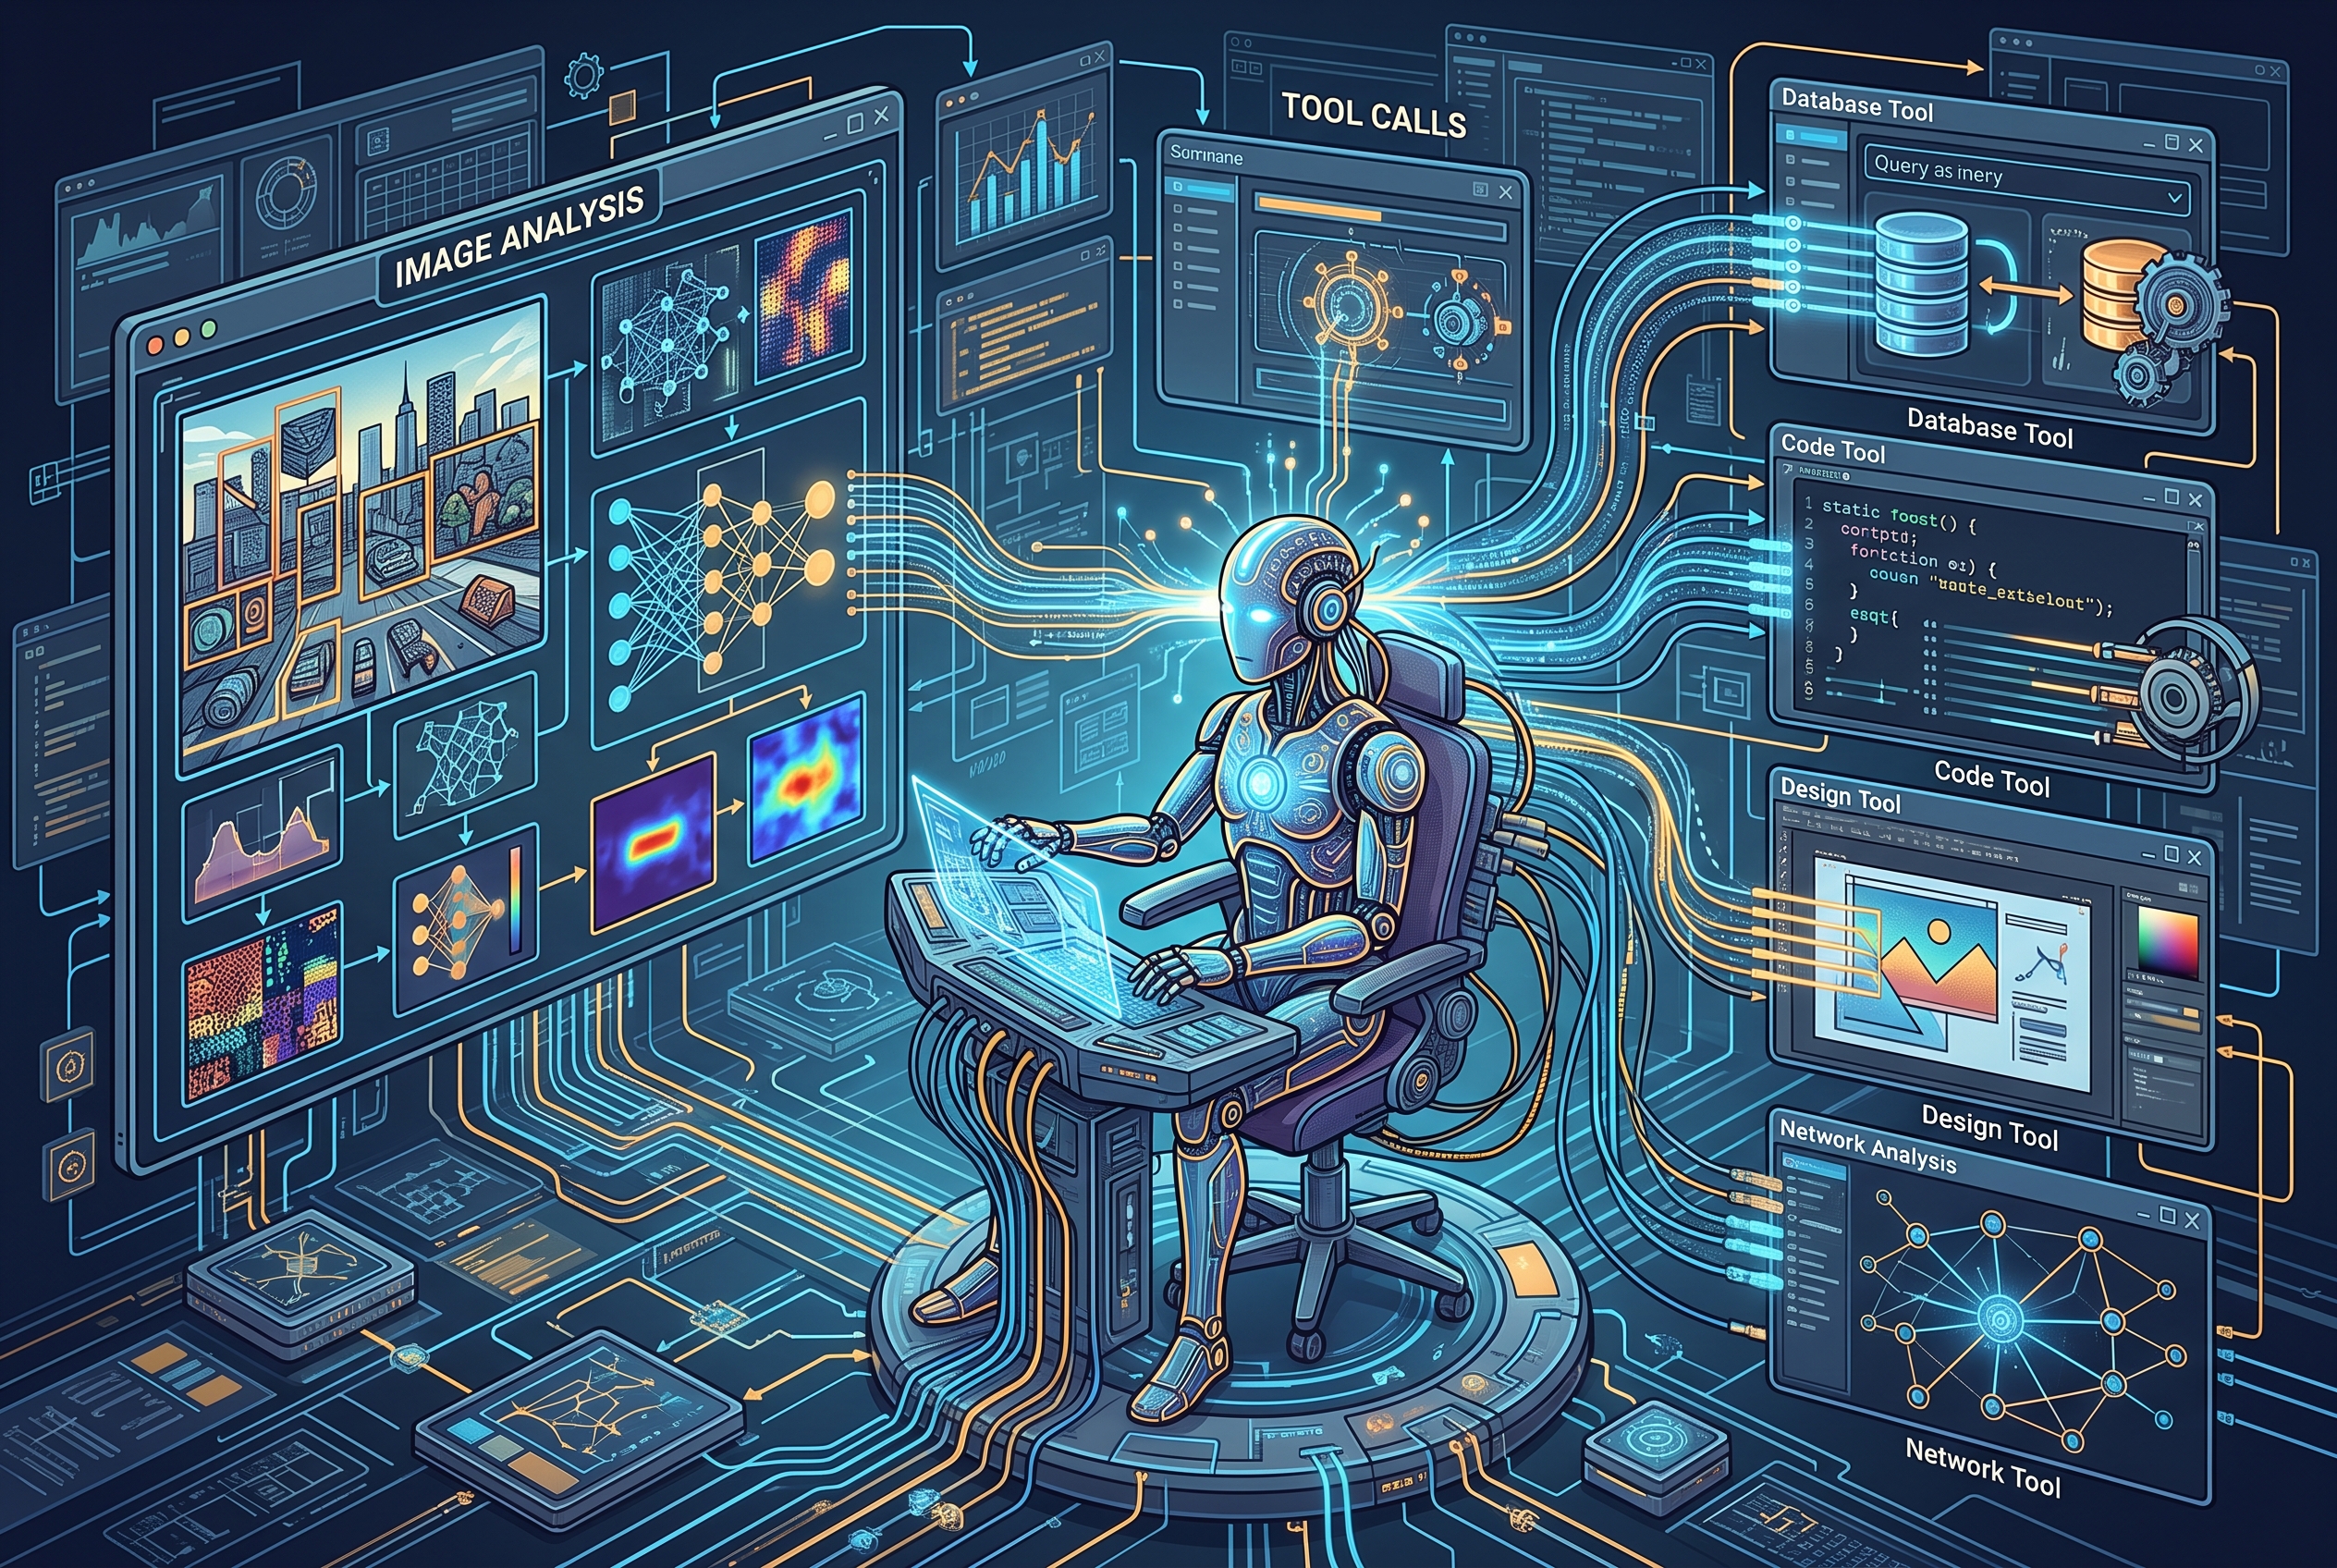
Document operations. Contract review, security questionnaires, and policy mapping often mix prose, tables, screenshots, and exceptions. Astra accepts image input through its Wiro configuration, so a workflow can include visual pages when layout changes the meaning. Require structured output with source references and confidence flags. A downstream system should receive fields that passed validation, not a free-form paragraph.
Practical operating rules
- Start with a budget. Set a maximum input size, tool-call count, wall-clock limit, and escalation path for each job type.
- Route reasoning deliberately. Use lower reasoning effort for extraction or classification. Reserve high, xhigh, or max for planning, verification, and hard exceptions.
- Keep evidence addressable. Give documents stable identifiers and ask the agent to cite them in its output. This makes review possible after a long run.
- Separate read and write tools. Let the agent inspect systems broadly, but require explicit approval before it changes records, deploys code, or sends external messages.
- Measure task outcomes. Compare completed, verified tasks against cost and latency. A faster model response is not a win if retries erase the gain.
OpenAI reports that Astra scored 72.6% on OSWorld 2.0 in a latency simulation at roughly 40 minutes per task, compared with 65.7% at roughly 75 minutes for GPT-5.6 Sol. Treat that as a vendor result, not a capacity plan. Reproduce the measurement with the browsers, tools, guardrails, and failure cases that match the real workflow.
Where to begin
Start with one workflow that currently loses important context between steps. Build a fixed evaluation set with known answers, messy inputs, tool failures, and cases where the correct action is to ask for help. Then test the same job at more than one context budget and reasoning level. The winning setup will usually be a clear workflow with selective long context, not the one that sends the most tokens.
For the underlying capabilities and evaluation claims, see the GPT-6 Astra launch details from OpenAI and the OpenAI prompt caching guide. Run GPT 6 Astra on Wiro with a bounded task, an explicit evidence format, and tool permissions that fit the risk.